Abstract
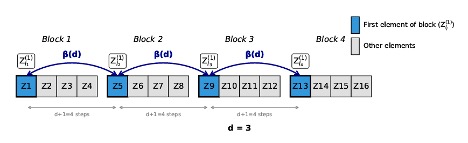
Temporal dependence makes raw sequence length a poor proxy for statistical information, yet temporal deep-learning benchmarks routinely compare regimes at fixed raw length N. We propose a dependence-aware evaluation protocol that matches an operational effective sample size Neff across regimes: estimate the integrated autocorrelation time on a pilot sample, allocate raw lengths to a common information budget, verify the achieved Neff, and report both the fixed-N and the matched view. Across more than 2,700 controlled runs spanning AR(1) and AR(2) processes, three architectures (TCN, LSTM, causal Transformer), and effective budgets from 50 to 4000, stronger dependence does not significantly increase train–test gaps in any matched cell; at scarce budgets the strongly dependent regime shows significantly smaller gaps, a contrast unchanged when every regime receives an identical number of optimizer updates, so it reflects information content rather than training exposure. A Beijing PM2.5 case study shows that which preprocessing appears best depends on the common information budget, an axis fixed-N evaluation cannot expose. We complement the protocol with a conservative generalization baseline for TCNs on exponentially β-mixing sequences, instantiating standard blocking with existing convolutional norm bounds; it controls population risk against an anchor empirical risk and serves as a worst-case reference for dependence and architecture scaling.
Under review.